Multilingual Language Model Fine-Tuning
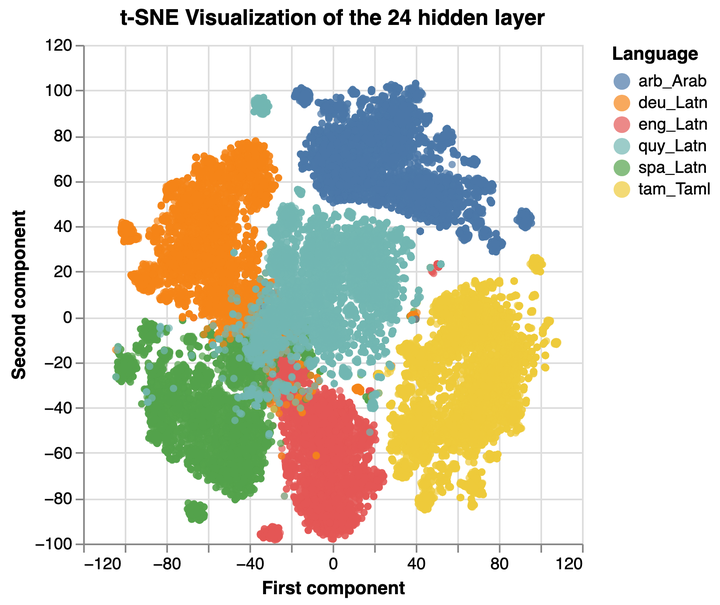 t-SNE projection of token representations from the 24th hidden layer, coloured by language.
We analyse how different fine-tuning methods affect language models on under-represented languages such as Quechua (quy_Latn). The methods we compare are full fine-tuning, BitFit, LoRA and IA3, applied to XGLM-564M and GPT-2 on multilingual corpora from NLLB.
Beyond the usual performance numbers, we look at what fine-tuning does to the models internally. Token and sentence representations are projected with PCA and t-SNE to see how the multilingual space is reorganised, which we then weigh against the performance trade-offs of each parameter-efficient method.